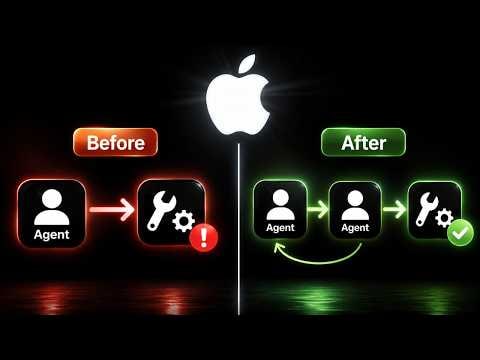
Apple Quietly Solved A Problem Every Tool-Calling Agent Has. Here's The Architecture.
The AI Automators16 June 2026Watch on YouTube
Description
👉 Access our AI Architects course & join hundreds of serious AI builders in our community: https://www.theaiautomators.com/?utm_source=youtube&utm_medium=video&utm_campaign=tutorial&utm_content=apple_tool_calling In this video, I break down a new paper from Apple on reinforced agents, a simple architecture that slides a reviewer agent into the loop ahead of tool execution to catch bad tool calls before they actually fire. I walk through how it works, what the helpfulness and harmfulness metrics actually show, where the approach falls short, and how it fits alongside other techniques like tool search and programmatic tool calling. Links: Video on tool search and programmatic tool calling: https://www.youtube.com/watch?v=R7OCrqyGMeY Research paper: https://machinelearning.apple.com/research/reinforced-agent-inference-feedback What happens when your AI agent makes a mistake you can't reverse? It might send the email, run the payment, or write to production before anyone notices. Agents often catch these errors, but usually right after they've happened, which is exactly when state recovery becomes complex, expensive, or impossible. What's covered: - How the reviewer agent acts as a gate ahead of tool execution and feeds rejections back to the main agent - The helpfulness vs harmfulness framing and why the 3:1 benefit-to-risk ratio is bounded by GPT-4o being used as the base agent throughout - Model choice for reviewer agents - The real costs: latency overhead and inference costs - Three collaboration patterns from the paper: progressive feedback, best-of-N selector, and best-of-N grading - How this complements Anthropic's tool search and programmatic tool calling rather than competing with them - Where reviewer gating fits best: irreversible actions like emails, payments, deletions, and production database writes - Why this is one of the few inference-time levers you can introduce without fine-tuning, training data, or extra orchestration infrastructure Chapters: 0:00 - The state recovery problem 0:32 - How the reviewer agent works 1:47 - Helpfulness vs harmfulness metrics 2:39 - Why GPT-4o as the base agent skews the numbers 3:42 - Prompt tuning cuts redundant loops 4:05 - Latency and cost overhead 4:52 - What the reviewer can and can't detect 6:27 - Three collaboration patterns 7:15 - How this compares to tool search and programmatic tool calling 8:20 - Where reviewer gating fits best
What you'll learn
- A reviewer agent can validate tool calls before execution, preventing irreversible errors such as sent emails or payments from occurring.
- The reviewer system acts as a gate in the agentic loop, rejecting bad tool calls and sending them back as feedback to the main agent for reconsideration.
- This is an inference-time solution that can be introduced without fine-tuning, training data, or additional orchestration in existing architectures.
- The approach carries latency and cost overhead due to extra model inference, especially when using the same capable models like GPT-4o for both agents.
- Reviewer gating works best for irreversible actions such as sending emails, payments, deletions, and production database writes.
Frequently asked questions
How does a reviewer agent prevent irreversible errors in agentic systems?
What are the main costs of the reviewer-gating system?
Which types of actions is reviewer-gating most suitable for?
How does reviewer-gating differ from techniques like tool search and programmatic tool calling?
Topics
In this video

Related reads
The speakers bringing HumanX to Amsterdam
HumanX Amsterdam opent op 22 september in de RAI met circa 200 sprekers, vijf tracks en drie dagen, waaronder oprichters van Legora, Lovable en Celonis naast enterprise-buyers van Diageo, ING en KLM.
Reaktor's first ecosystem company co-founded in the Netherlands
Reaktor Ecosystem heeft zijn eerste bedrijf in Nederland mede opgericht: GAIA Technology Systems BV, een AI-native software development consultancy gevestigd in Amsterdam, vier maanden na de opening van Reaktors Amsterdam-hub in mei 2026.