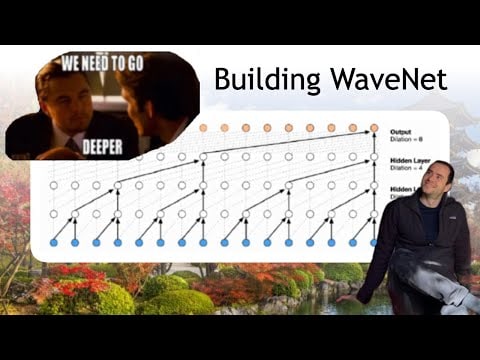
Building makemore Part 5: Building a WaveNet
Andrej Karpathy16 June 2026Watch on YouTube
Part of series
Ep. 1 · Building Makemore Part
View the seriesWhat you'll learn
- You learn how to extend a simple MLP into a deeper CNN architecture with a tree-like structure, similar to DeepMind's WaveNet.
- You understand the role of dilated convolutions in efficiently implementing hierarchical architectures for sequential data.
- You gain practical insights into using PyTorch and torch.nn for implementing complex neural networks.
- You see how to tackle debugging challenges in deep learning, such as fixing BatchNorm1d bugs and monitoring tensor dimensions.
- You learn what a typical deep learning development process looks like: reading documentation, tracing tensor shapes, and iterative experimentation.
Frequently asked questions
How does WaveNet differ from the simple MLP model from the previous video?
What are dilated convolutions and why are they useful in WaveNet?
What kind of bug was encountered with BatchNorm1d and how was it fixed?
How is the practical deep learning development cycle visible in this tutorial?
Topics
In this video

Description from the channel
We take the 2-layer MLP from previous video and make it deeper with a tree-like structure, arriving at a convolutional neural network architecture similar to the WaveNet (2016) from DeepMind. In the WaveNet paper, the same hierarchical architecture is implemented more efficiently using causal dilated convolutions (not yet covered). Along the way we get a better sense of torch.nn and what it is and how it works under the hood, and what a typical deep learning development process looks like (a lot of reading of documentation, keeping track of multidimensional tensor shapes, moving between jupyter notebooks and repository code, ...). Links: - makemore on github: https://github.com/karpathy/makemore - jupyter notebook I built in this video: https://github.com/karpathy/nn-zero-to-hero/blob/master/lectures/makemore/makemore_part5_cnn1.ipynb - collab notebook: https://colab.research.google.com/drive/1CXVEmCO_7r7WYZGb5qnjfyxTvQa13g5X?usp=sharing - my website: https://karpathy.ai - my twitter: https://twitter.com/karpathy - our Discord channel: https://discord.gg/3zy8kqD9Cp Supplementary links: - WaveNet 2016 from DeepMind https://arxiv.org/abs/1609.03499 - Bengio et al. 2003 MLP LM https://www.jmlr.org/papers/volume3/bengio03a/bengio03a.pdf Chapters: intro 00:00:00 intro 00:01:40 starter code walkthrough 00:06:56 let’s fix the learning rate plot 00:09:16 pytorchifying our code: layers, containers, torch.nn, fun bugs implementing wavenet 00:17:11 overview: WaveNet 00:19:33 dataset bump the context size to 8 00:19:55 re-running baseline code on block_size 8 00:21:36 implementing WaveNet 00:37:41 training the WaveNet: first pass 00:38:50 fixing batchnorm1d bug 00:45:21 re-training WaveNet with bug fix 00:46:07 scaling up our WaveNet conclusions 00:46:58 experimental harness 00:47:44 WaveNet but with “dilated causal convolutions” 00:51:34 torch.nn 00:52:28 the development process of building deep neural nets 00:54:17 going forward 00:55:26 improve on my loss! how far can we improve a WaveNet on this data?