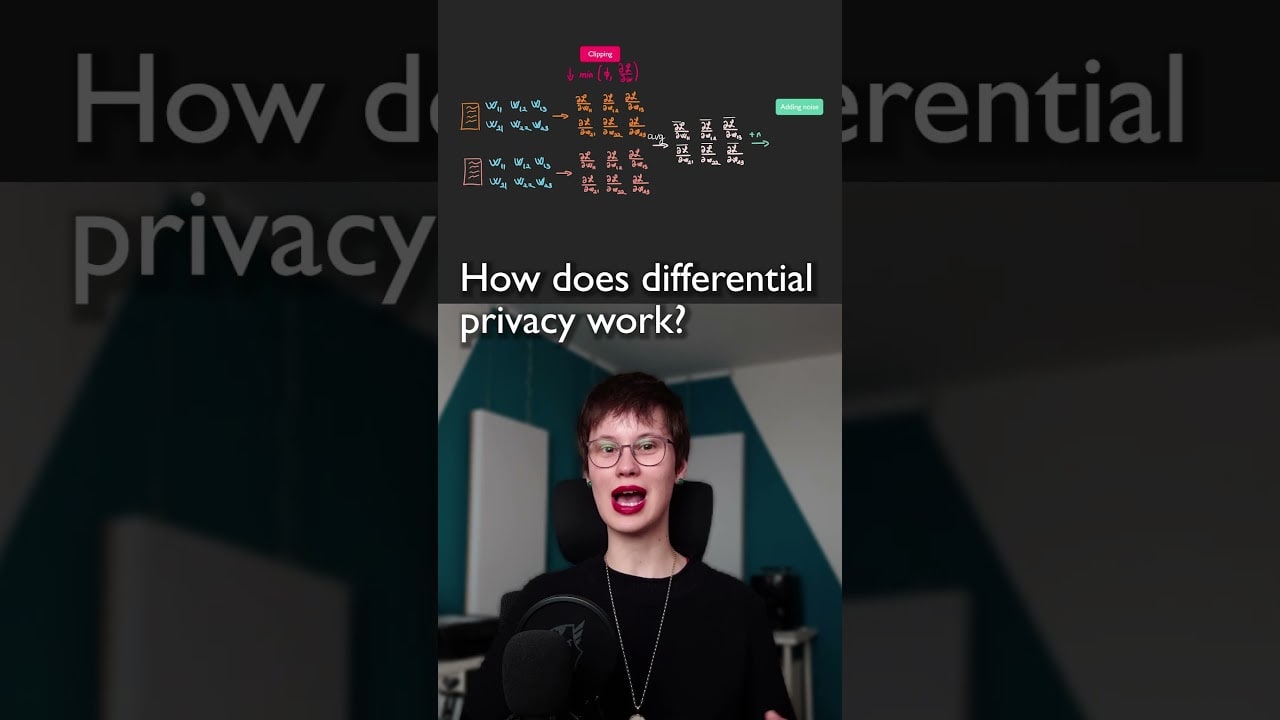
Differential Privacy in 30 seconds
AI Coffee Break with Letitia16 June 2026Watch on YouTube
Description
Full video: 🎥 https://youtu.be/UwX5zzjwb_g Large language models often memorize what they see — even a single phone number or address can stick forever in their weights. Google’s new VaultGemma changes that: it’s the first open-weight LLM trained from scratch with differential privacy, meaning secrets seen seldomly during training leaves no trace. 👉 In this video, we explain Differential Privacy through the concrete example of VaultGemma — how it works, why it matters, and what it means for the future of trustworthy AI. AI Coffee Break Merch! 🛍️ https://aicoffeebreak.creator-spring.com/ Thanks to our Patrons who support us in Tier 2, 3, 4: 🙏 Vignesh Valliappan, Ivan Janov, Sunny Dhiana, Andy Ma ▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀ 🔥 Optionally, pay us a coffee to help with our Coffee Bean production! ☕ Patreon: https://www.patreon.com/AICoffeeBreak Ko-fi: https://ko-fi.com/aicoffeebreak Join this channel as a Bean Member to get access to perks: https://www.youtube.com/channel/UCobqgqE4i5Kf7wrxRxhToQA/join ▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀▀ 🔗 Links: AICoffeeBreakQuiz: https://www.youtube.com/c/AICoffeeBreak/community Twitter / X: https://twitter.com/AICoffeeBreak LinkedIn: https://www.linkedin.com/in/letitia-parcalabescu/ Threads: https://www.threads.net/@ai.coffee.break Bluesky: https://bsky.app/profile/aicoffeebreak.bsky.social Reddit: https://www.reddit.com/r/AICoffeeBreak/ YouTube: https://www.youtube.com/AICoffeeBreak Substack: https://aicoffeebreakwl.substack.com/ Web: https://explanationmark.de/letitia https://aicoffeebreak.com #AICoffeeBreak #MsCoffeeBean #MachineLearning #AI #research Video editing: Nils Trost
What you'll learn
- Differential privacy is a technique that allows large language models to be trained without sensitive training data becoming permanently stored in model weights
- VaultGemma is the first open-weight LLM trained from scratch with differential privacy by Google Research
- Differential privacy prevents rarely seen secrets from training data, such as phone numbers or addresses, from being permanently retained in the model
Frequently asked questions
What is the problem with standard large language models and training data?
How does differential privacy solve this problem?
What makes VaultGemma special?
Topics
In this video
Related reads
Google klaagt Chinese cybercrimegroep aan voor AI-fraude
Google stelt dat een Chinese organisatie AI gebruikt voor frauduleuze activiteiten en stapt daarin samen met de FBI en Amerikaanse providers naar de rechter.
OpenAI mikt op lang draaiende agents met overname van Ona
OpenAI neemt Ona over, voorheen bekend als Gitpod, een startup die AI-agents laat draaien in cloud sandboxes. De overname versterkt Codex en stelt OpenAI in staat agents taken te laten uitvoeren die uren of dagen in beslag nemen.
Apple zou in overleg zijn met Anthropic en Google over Siri-alternatieven
Apple overlegt naar verluidt met Anthropic en Google over het beschikbaar stellen van hun AI-chatbots als alternatief voor Siri via een extensiesysteem.
Google, Anthropic en AMD kondigen nieuwe AI-modellen en chips aan
Google presenteerde Gemini 3.5 Flash en de AI-agent Gemini Spark tijdens Google I/O 2026, Anthropic bracht Claude Sonnet 5 en Opus 5 uit, en AMD introduceerde zijn Helios AI-rack op het Advancing AI 2026-evenement in San Francisco.
Google brengt AI-weermodel WeatherNext 3 uit
Wetenschappers van Google DeepMind en Google Research hebben het AI-weermodel WeatherNext 3 uitgebracht dat het weer gedetailleerder en vaker voorspelt.
Okta en Google Cloud beveiligen AI-agents
Okta en Google Cloud breiden samenwerking uit met nieuwe veiligheidsoplossingen voor AI-agents en verbeterde browserbescherming.