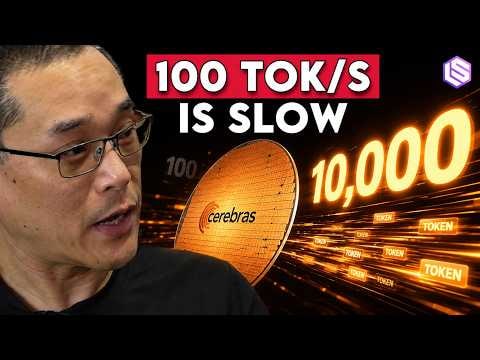
The Inference Frontier: from 100 to 10,000 tokens per second — Sean Lie, Cerebras CTO
Latent Space2 September 2026Watch on YouTube
What you'll learn
- You learn how Cerebras accelerates inference with CS4 and CS5 to beyond 4,000 tokens per second and toward 10,000 tokens per second.
- You discover why Cerebras argues that 100 to 200 tokens per second may soon feel like batch mode.
- You understand how the partnership with OpenAI and the Jalapeño chip could form a new inference stack.
- You get insight into Sean Lie's critique of Groq and the limits of SRAM architectures for frontier-scale models.
- You learn why the future of AI infrastructure is becoming heterogeneous and disaggregated, from memory bandwidth to 3D integration and the US-China race.
Frequently asked questions
Why does Cerebras argue that 100 to 200 tokens per second may soon feel like batch mode?
How does Cerebras work with OpenAI in this episode?
What is Sean Lie's critique of Groq and SRAM architectures?
Why is Cerebras said to be sold out of its current capacity?
Topics
In this video
Read next
OpenAI aangeklaagd in zelfdodingszaak ChatGPT-gebruiker
OpenAI en ceo Sam Altman zijn in de VS aangeklaagd door een Canadese moeder die stelt dat haar dochter door ChatGPT is aangezet tot zelfdoding.
OpenAI mikt op lang draaiende agents met overname van Ona
OpenAI neemt Ona over, voorheen bekend als Gitpod, een startup die AI-agents laat draaien in cloud sandboxes. De overname versterkt Codex en stelt OpenAI in staat agents taken te laten uitvoeren die uren of dagen in beslag nemen.
OpenAI lanceert omstreden model Astra
OpenAI stelt dat Astra een 'nieuwe grens' vormt voor computer- en browsertaken en taken uitvoert met ongeëvenaarde snelheid, nauwkeurigheid en veiligheid.
OpenAI noemt GPT-6 Astra 'generatiesprong in kunnen'
OpenAI omschrijft GPT-6 Astra als een 'generatiesprong in kunnen' voor onder meer cybersecurity, software-engineering en computergebruik, en als eerste model dat de 'kritieke cybersecurity-drempel' haalt.
OpenAI boekte bijna 39 miljard dollar verlies in 2025
Volgens uitgelekte documenten liep OpenAI's verlies vorig jaar fors op tot 38,53 miljard dollar bij een omzet van 13,07 miljard dollar.
ChatGPT en Codex getroffen door storing bij OpenAI
OpenAI kampt met een storing waardoor ChatGPT en Codex slecht bereikbaar zijn; het bedrijf doet onderzoek en geeft geen details of verwachte oplossing.
Description from the channel
From pushing inference beyond 4,000 tokens per second to working with OpenAI on a new generation of ultra-fast AI infrastructure, Cerebras is betting that speed doesn’t just make models faster, it makes entirely new kinds of AI possible. In this episode, Cerebras co-founder and CTO Sean Lie joins swyx and Vibhu fresh off Hot Chips to unpack CS4, preview CS5, and explain why 100–200 tokens per second may soon feel like “batch mode.” We go deep on Cerebras’ wafer-scale architecture, its partnership with OpenAI, and the emerging hardware stack for frontier inference. Sean breaks down OpenAI’s Jalapeño chip, why AI-first chip design could transform the semiconductor industry, what NVIDIA, Groq, AMD, Etched, and other challengers are getting right and wrong, and why the future of AI infrastructure will increasingly be heterogeneous and disaggregated. We also discuss model-hardware co-design, the path toward 10,000-token-per-second inference, new approaches to memory and 3D packaging, and the growing strategic competition between the US and China across both models and semiconductors. We discuss: • Why Cerebras believes 100–200 tokens per second is becoming the new “batch mode” • CS4 and how Cerebras is pushing inference beyond 4,000 tokens per second • CS5 and the path toward 10,000 TPS on medium-sized models • Running frontier models at up to 5,000 tokens per second • Why Cerebras is effectively sold out of its current capacity • How OpenAI is using ultra-fast inference internally for incident response and critical research • Why faster inference can enable more reasoning loops and more capable agents • OpenAI’s Jalapeño chip and why Sean sees AI-first chip design as the future • How Cerebras and OpenAI could combine CS5 and Jalapeño into a new inference stack • Sean’s critique of Groq and the limitations of SRAM architectures for frontier-scale models • Why inference is breaking apart into specialized workloads like prefill, decode, attention, and expert routing • Why future data centers may increasingly be designed like one giant computer • How models designed around NVIDIA GPUs leave performance gains on the table for alternative architectures • Why hardware-model co-design could unlock massive additional gains • NVIDIA, AMD, TPU, and Trainium — and where traditional accelerator architectures are heading • Sean’s take on Etched and what next-generation AI hardware startups should actually innovate on • Why memory bandwidth, 3D integration, power, and cooling are becoming central bottlenecks • The rise of Chinese open models and China’s increasingly independent AI hardware ecosystem — Sean Lie • Cerebras: https://www.cerebras.ai/ • X: https://x.com/seanlie Timestamps 00:00:00 Hook 00:01:19 Introduction 00:03:40 CS4 and 4,400 Tokens Per Second 00:07:07 From “Impossible” Wafer Scale to OpenAI 00:10:13 CS5 and the Road to 10,000 TPS 00:12:05 Cerebras Is Sold Out — and OpenAI Wants the Capacity 00:14:53 Why OpenAI Is Sharing Ultra-Fast Inference 00:15:53 OpenAI Jalapeño and AI-Designed Chips 00:20:11 Performance, Power, and the Groq Debate 00:21:44 Groq’s 31B Benchmark and SRAM Limitations 00:24:44 The Future of Heterogeneous AI Inference 00:26:35 Breaking Inference Into Specialized Hardware 00:29:41 Model-Hardware Co-Design 00:32:00 NVIDIA, AMD, TPU, and Trainium 00:33:44 Sean’s Take on Etched 00:35:30 Why the Next Breakthrough Goes Beyond the Chip 00:38:31 Memory Bandwidth and 3D Integration 00:39:19 Power, Cooling, and the Hard Parts of Wafer Scale 00:40:42 China, Open Models, and the Semiconductor Race 00:43:04 Cerebras’ IPO and Closing Thoughts